The Architecture of Control
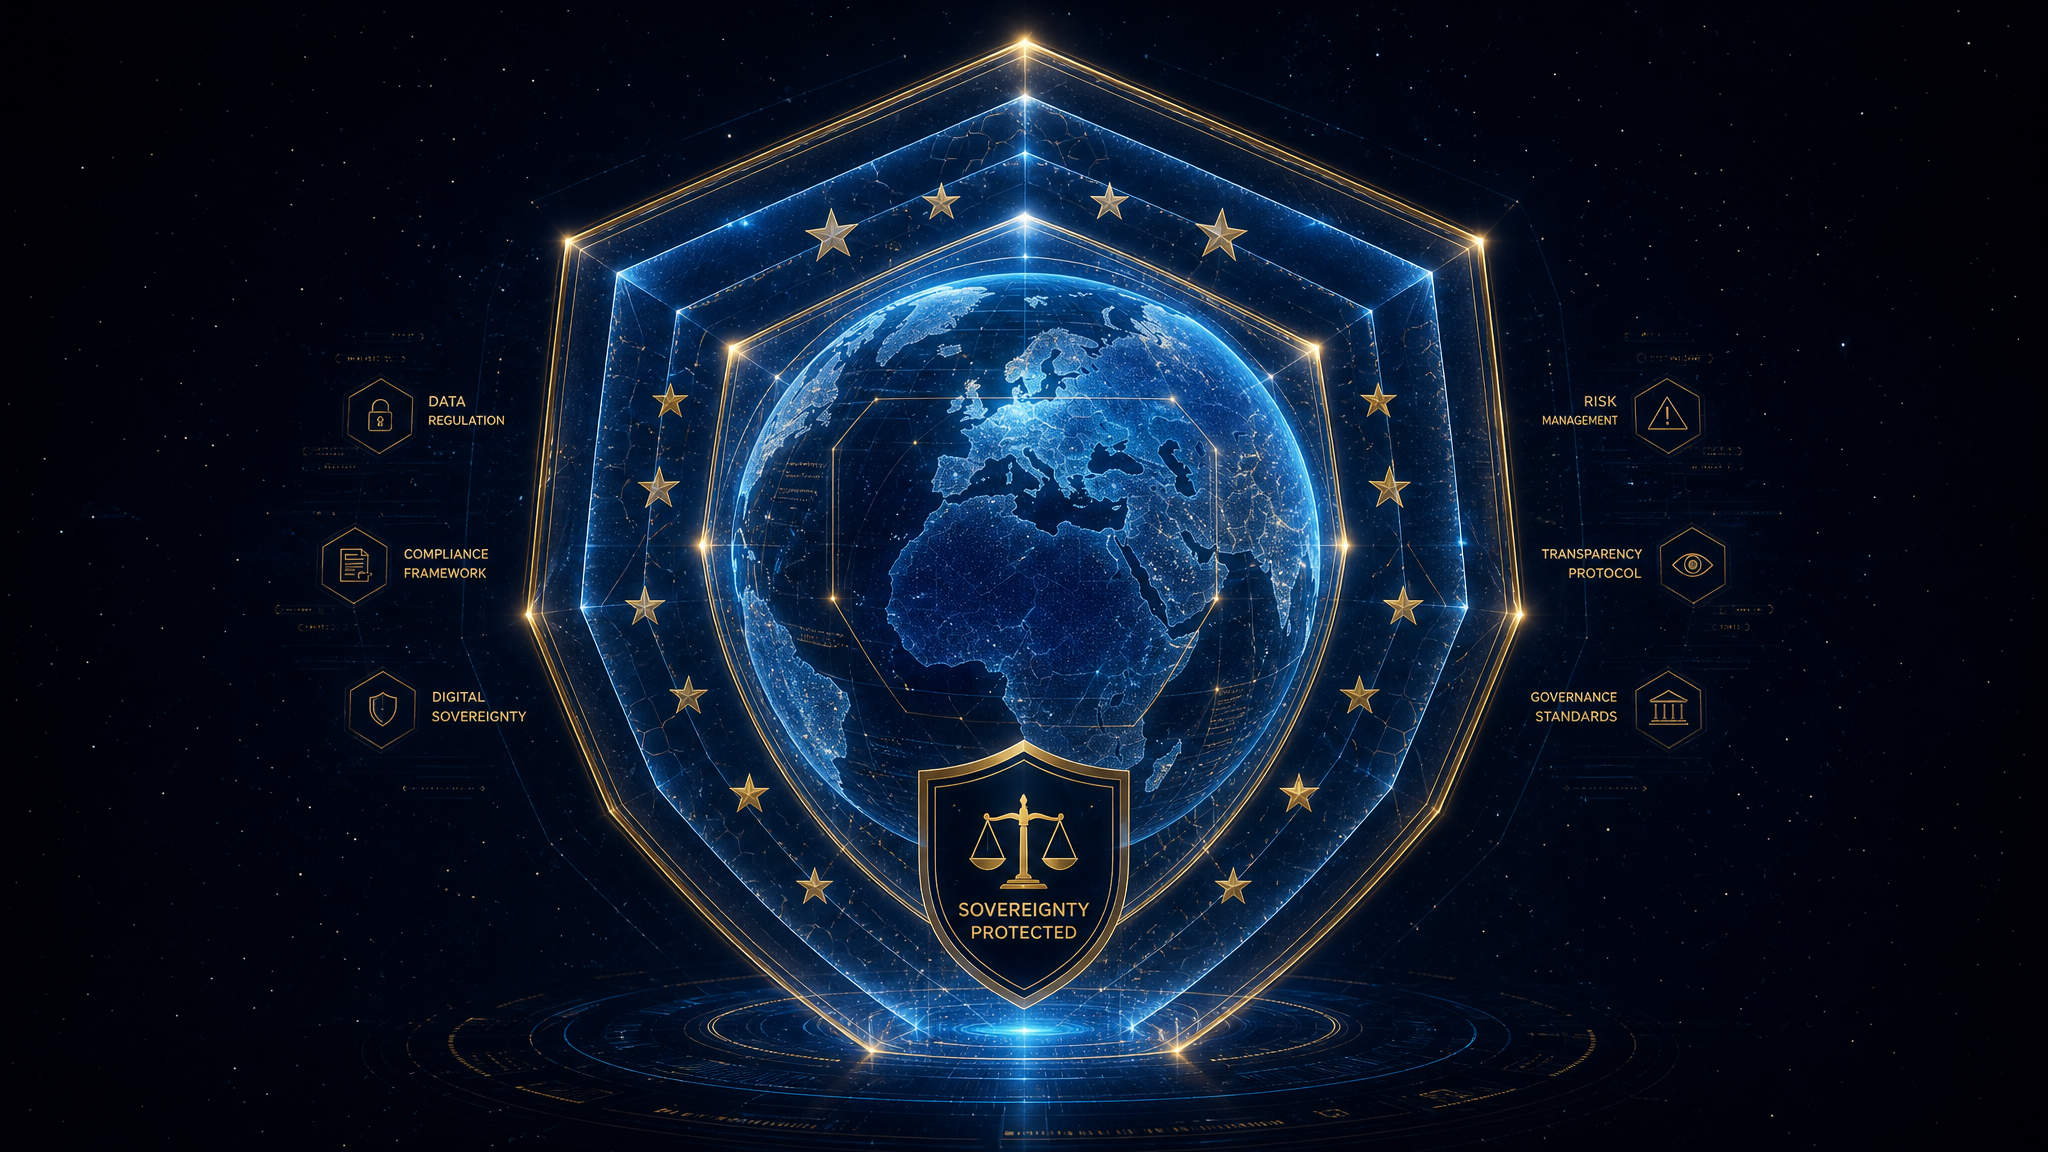
On 2 August 2026, the European Union AI Act's obligations for high-risk AI systems became fully enforceable. The date passed without the fanfare that accompanied the regulation's initial adoption, but its practical consequences are reshaping the architecture of AI deployment across every sector. Article 10 of the Act mandates stringent data governance practices for providers of high-risk AI systems: documented proof of training data origin, bias examination, and data quality controls. Non-compliance carries penalties of up to €15 million or 3 per cent of global annual turnover. The message is unambiguous: the era of deploying AI systems without accountability for the data they consume is over.
But the EU AI Act is only the most visible element of a broader structural shift. Over 34 countries have enacted data localisation laws. The collapse of the EU-US Data Privacy Framework in 2025 has left transatlantic data flows in a state of legal uncertainty. The US CLOUD Act continues to allow American authorities to compel access to data held by US-incorporated firms regardless of where that data is physically stored — a provision that makes "data residency" in a European data centre a necessary but insufficient condition for genuine data sovereignty when the cloud provider is headquartered in the United States.
The result is a moment of structural reckoning for anyone who relies on AI systems — which, in 2026, means almost everyone. The question of who controls the intelligent layer of daily life — who holds the keys to the models that draft our communications, analyse our health data, manage our finances, and increasingly make decisions that affect our opportunities and freedoms — is no longer a philosophical abstraction. It is a legal, technical, and strategic question with concrete answers that vary depending on the architecture choices made today.
Data residency tells you where your data sleeps. Data sovereignty tells you who holds the keys — and in 2026, those are very different questions with very different legal consequences.
Residency vs. Sovereignty: A Critical Distinction
The most important conceptual clarification in the current landscape is the distinction between data residency and data sovereignty. Data residency refers to the physical location of servers — where data is stored. Data sovereignty refers to legal and technical control — who has the authority to access, modify, or compel disclosure of that data, and under which jurisdiction's laws.
The distinction matters because residency without sovereignty is a false assurance. An organisation that stores its data in a European data centre operated by a US-headquartered cloud provider has achieved residency but not sovereignty. The US CLOUD Act means that American authorities can compel the provider to disclose that data regardless of its physical location. The European Data Protection Board has identified this as a fundamental sovereignty gap — one that cannot be resolved by contractual commitments alone, because the provider's legal obligations to US authorities override its contractual obligations to European customers.
True data sovereignty requires that the legal jurisdiction governing the data, the technical infrastructure processing it, and the operational staff managing it all fall within the same sovereign boundary — or that the data is encrypted in ways that make it technically inaccessible to the provider, regardless of legal compulsion. This is a significantly higher bar than residency, and it is the bar that the EU AI Act's enforcement regime is effectively setting.
The On-Device Revolution
Data residency tells you where your data sleeps. Data sovereignty tells you who holds the keys — and in 2026, those are very different questions with very different legal consequences.
The most significant structural response to the sovereignty imperative has been the rapid shift towards on-device and on-premise AI inference. According to analysis from Crewdle, over 55 per cent of enterprise AI inference now occurs on-premise or on-device — a dramatic increase from 12 per cent in 2023. This shift is driven by a convergence of regulatory pressure, economic incentive, and technological capability.
Over 55 per cent of enterprise AI inference now occurs on-premise or on-device, up from 12 per cent in 2023 — a structural shift driven not by ideology but by the hard economics of compliance and latency.
The economic case is compelling independent of regulation. Local inference is often 18 times cheaper per token than cloud-based inference, and provides sub-50 millisecond latency that is critical for real-time applications. The regulatory case is equally compelling: on-premise inference eliminates cross-border data transfer risks entirely, providing what the European Data Protection Board has characterised as the strongest available mitigation for LLM data privacy. The combination of cost, performance, and compliance advantages is driving adoption at a pace that would have seemed implausible three years ago.
The technological enablers of this shift are the availability of high-performance hardware in configurations that were previously only viable at hyperscaler scale. NVIDIA's B200 and H100 systems, deployed in European data centres and increasingly in on-premise configurations, have eliminated the performance trade-off that previously made local inference a compromise. Organisations no longer face a choice between frontier model performance and regulatory compliance — they can have both, provided they are willing to invest in the infrastructure.
For individuals, the on-device AI revolution is manifesting in a new generation of privacy-first AI assistants. Tools such as LMSA, Jan.ai, and PrivateLLM execute queries entirely on the user's hardware, ensuring 100 per cent data isolation. Services like Proton's Lumo AI apply end-to-end encryption, ensuring that even the provider cannot read the data. Anonymising proxies like Duck.ai and Brave Leo strip away IP addresses and personal identifiers before routing queries to cloud models, shielding user identity while preserving access to powerful frontier capabilities.
A Framework for Personal AI Sovereignty
The proliferation of privacy-first AI tools and the maturation of the regulatory environment make it possible, for the first time, to articulate a coherent framework for personal AI sovereignty. This framework operates across four dimensions: data control, model transparency, jurisdictional clarity, and operational accountability.
Dimension 1: Data Control
Data control is the foundational dimension. It encompasses three distinct questions: where is the data processed, who has access to it, and what happens to it after processing. The gold standard for data control is on-device processing with no external transmission — the model runs locally, the data never leaves the device, and there is no third party with access to either the query or the response. Where on-device processing is not feasible, the next best option is zero-knowledge encryption, in which the data is encrypted before transmission and the provider holds no decryption keys. The weakest acceptable option is a contractually binding "no-training" commitment from a provider that is subject to a jurisdiction with strong data protection enforcement.
The "no-training" commitment has become a baseline expectation in the market. Privacy-conscious users and organisations should verify that the provider is contractually bound not to use inputs for model improvement, and should treat any provider that cannot make this commitment as incompatible with a sovereignty-first approach. The EU AI Act's requirements for documented training data provenance create additional pressure on providers to be transparent about what data their models were trained on — a requirement that extends, by implication, to the data used to fine-tune or update those models after deployment.
Dimension 2: Model Transparency
Over 55 per cent of enterprise AI inference now occurs on-premise or on-device, up from 12 per cent in 2023 — a structural shift driven not by ideology but by the hard economics of compliance and latency.
Model transparency addresses the question of what the AI system is doing and why. For high-risk AI systems under the EU AI Act, transparency is a legal requirement: providers must be able to explain how their systems make decisions, what data they were trained on, and what safeguards are in place against bias and error. For personal AI assistants, the transparency requirements are less prescriptive but no less important.
The emerging standard for model transparency in personal AI contexts includes: disclosure of the model architecture and training data sources; documentation of the system's known limitations and failure modes; and the ability for users to audit the system's outputs and flag errors. The "Insights, Not Data" architecture — in which sensitive information is pseudonymised or aggregated locally before being sent to a cloud model — represents one approach to balancing transparency with performance, ensuring that the model receives sufficient context to be useful without exposing proprietary or sensitive data.
Dimension 3: Jurisdictional Clarity
Jurisdictional clarity addresses the question of which legal system governs the AI system and the data it processes. This is not merely a question of where the servers are located — it is a question of where the provider is incorporated, which courts have jurisdiction over disputes, and which regulatory authorities have oversight. The collapse of the EU-US Data Privacy Framework has made this question more complex for transatlantic deployments, but it has also clarified the stakes: organisations that cannot answer the jurisdictional question with confidence are operating with unquantified legal risk.
The sovereign cloud market — infrastructure operated by entities that are legally and operationally subject to a single jurisdiction — is projected to reach approximately $195 billion in 2026, with a 35.6 per cent increase in spending on sovereign cloud infrastructure as a service. This growth reflects the recognition that jurisdictional clarity is not a luxury but a compliance requirement for organisations operating in regulated sectors or handling sensitive data.
Dimension 4: Operational Accountability
Operational accountability addresses the question of what happens when things go wrong. AI systems make errors. They can be manipulated through adversarial inputs. They can produce outputs that are harmful, inaccurate, or discriminatory. The question is not whether these failures will occur but whether there is a mechanism for identifying them, correcting them, and holding the responsible parties accountable.
The EU AI Act's requirements for conformity assessments, audit trails, and post-market monitoring create a framework for operational accountability for high-risk AI systems. For personal AI assistants, the accountability framework is less developed, but the direction of travel is clear: users are increasingly demanding the ability to understand, audit, and contest the decisions made by AI systems that affect their lives. The right to explanation — the ability to understand why an AI system made a particular decision — is emerging as a foundational element of personal AI sovereignty.
The Geopolitics of AI Sovereignty
The personal AI sovereignty framework does not exist in a geopolitical vacuum. Governments are increasingly treating AI infrastructure as a national security asset. Saudi Arabia, Germany, France, and a growing number of other nations are funding domestic compute clusters, treating GPU capacity as a strategic resource analogous to energy reserves or military hardware. The concept of "geopatriation" — the repatriation of AI infrastructure to domestic or allied jurisdictions — is moving from academic discussion to policy implementation.
The EU AI Act's August 2026 enforcement deadline did not merely change compliance checklists — it changed the fundamental architecture of what it means to deploy AI responsibly.
This geopolitical dimension has direct implications for personal AI sovereignty. An individual or organisation that relies on AI infrastructure controlled by a foreign government — or by a company subject to foreign legal jurisdiction — is exposed to risks that go beyond data privacy. The AI systems that manage critical infrastructure, financial systems, healthcare, and communications are potential vectors for geopolitical leverage. The nation that controls the AI layer controls, to a significant degree, the decisions made by that layer.
The response to this risk is not autarky — the complete withdrawal from international AI infrastructure — but diversification and sovereignty by design. Organisations that build AI architectures with sovereignty as a foundational principle, rather than a compliance afterthought, are better positioned to navigate the geopolitical landscape. They can switch providers, migrate workloads, and adapt to changing regulatory requirements without the disruption that comes from having built on a foundation of assumed trust.
The EU AI Act's August 2026 enforcement deadline did not merely change compliance checklists — it changed the fundamental architecture of what it means to deploy AI responsibly.
The Provenance Problem
One of the most significant emerging challenges in personal AI sovereignty is the provenance problem: the question of what data was used to train the AI systems that individuals and organisations rely on. The EU AI Act's Article 10 requirements for documented training data provenance are creating pressure on providers to be transparent about their training pipelines — but the complexity of modern AI development makes full transparency difficult to achieve.
Large language models are trained on datasets that may include billions of documents from thousands of sources, processed through multiple stages of filtering, fine-tuning, and reinforcement learning. Tracing the provenance of a specific output to a specific training document is technically challenging and often impossible. Yet the legal and ethical implications of training data provenance are significant: if a model was trained on data that crossed restricted borders, was collected without consent, or included copyrighted material, the organisations deploying that model may be exposed to legal liability.
The emerging response to the provenance problem is the development of "provenance metadata" — structured records that track the lineage of AI models from training data through deployment. This metadata enables organisations to verify that the AI systems they deploy were trained on compliant data, to identify and mitigate risks associated with specific training sources, and to demonstrate compliance with regulatory requirements. The development of standards for AI provenance metadata is one of the most important governance challenges of the current moment.
Conclusion: Sovereignty as Architecture
Personal AI sovereignty is not a preference or a political position — it is an architectural choice with legal, economic, and strategic consequences. The organisations and individuals that treat sovereignty as a foundational design principle, rather than a compliance checkbox, will be better positioned to navigate the regulatory landscape, manage geopolitical risk, and maintain the trust of the communities they serve.
The framework presented here — data control, model transparency, jurisdictional clarity, and operational accountability — provides a structure for making those architectural choices systematically. It is not a complete solution to the challenges of AI governance, which extend far beyond the individual and organisational level to encompass the design of AI systems, the governance of AI infrastructure, and the distribution of AI's benefits and risks across society. But it is a starting point for the most important question of the current moment: who holds the keys to the intelligent layer of daily life?
The answer to that question will shape the relationship between individuals, institutions, and AI systems for decades to come. The architectural choices being made today — in data centres, in boardrooms, in regulatory agencies, and in the design of personal AI assistants — are the choices that will determine whether AI sovereignty becomes a reality or remains an aspiration. The window for making those choices well is open. It will not remain open indefinitely.